We are fully licensed across the UK, Ireland, Switzerland, Germany and the USA, enabling us to support customers with compliant cross-border talent acquisition.
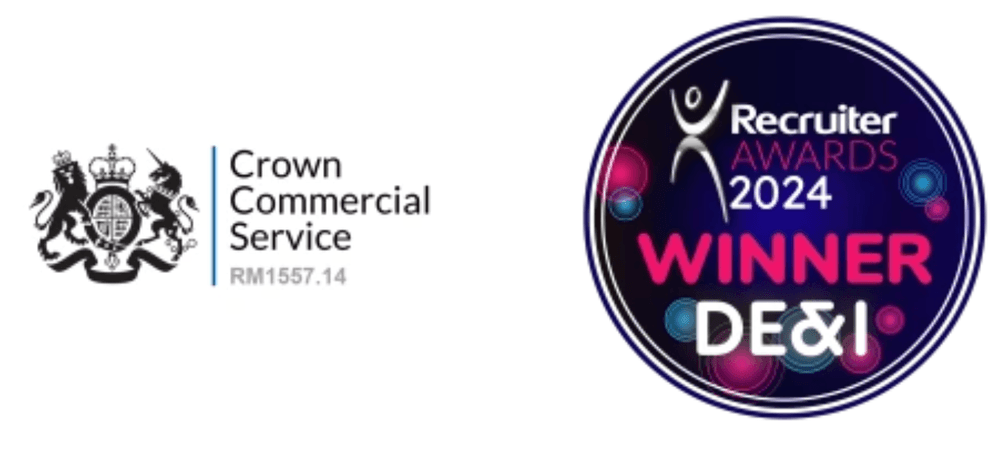
Introducing DeepRec.ai's Hertfordshire HQ, our basecamp for connecting incredible candidates with Deep Tech opportunities across the globe.
SALARY GUIDE
Built with fresh insights from our talent network, we developed this guide for anyone hoping to benchmark salaries, align remuneration with the wider market, or learn more about the trends and opportunities across the German Deep Tech space. Download your copy here:
INSIGHTS
Building AI Teams at Startup Speed: Scaling Specialist Talent Across Switzerland and the US
 Anthony Kelly
11 days ago
DeepRec.ai partners with Mistral to support the growth of its Applied AI team
 Hayley Killengrey
about 1 month ago
Scaling AI Teams: A Guide to High-Volume Hiring
Hayley Killengrey2 months ago
Ethical AI Starts with Responsible Hiring Decisions
Anthony Kelly3 months ago
LATEST JOBS
San Fran, United States
ML Engineer
Permanent
Machine Learning Engineer – Reinforcement Learning & Simulation
Location: San Francisco, CA
Working Arrangement: Full-time, office-based
Compensation: $120,000–$220,000 base salary + equity
About the Opportunity
We’re partnering with an ambitious, well-funded AI startup working at the intersection of machine learning, reinforcement learning, simulation, and robotics.
The company is building infrastructure to train, evaluate, and improve next-generation AI models, combining advanced simulation environments with substantial real-world robotics infrastructure. Having established a significant operational foundation, the team is now focused on scaling the engineering systems that enable reinforcement learning environments to be developed, tested, and deployed at pace.
This is an opportunity to join a small, exceptionally driven technical team at an early stage, with significant ownership over core systems and the chance to help shape engineering standards as the company grows.
The Role
We’re looking for a strong Machine Learning Engineer with excellent technical fundamentals and an interest in reinforcement learning, simulation, and AI systems.
Your primary focus will be scaling the production of reinforcement learning environments, turning research requirements into robust, efficient, and maintainable software systems. You’ll work closely with researchers to build the infrastructure needed to run simulations at scale and support the training and evaluation of advanced AI models.
This is a highly engineering-focused role. You won’t necessarily need to develop novel reinforcement learning algorithms or have an extensive robotics background. Instead, we’re looking for someone who can build excellent software, solve difficult technical problems, and learn new concepts quickly.
For more experienced candidates, there is also scope to take on greater technical ownership, mentor other engineers, and help establish the engineering practices that will support the team's next phase of growth.
What You’ll Be Doing
Build, scale, and productionise reinforcement learning environments used to train and evaluate advanced AI models.
Translate research ideas and experimental requirements into reliable, high-performance engineering systems.
Develop infrastructure to run simulation environments efficiently and at scale.
Improve software quality, maintainability, testing, and engineering standards across the team.
Collaborate with research colleagues to identify which environments and approaches deliver measurable improvements in model performance.
Support model post-training, evaluation, and benchmarking where appropriate.
Help validate simulation results through real-world model evaluation and testing on robotic systems.
Identify opportunities to improve performance, scalability, and the efficiency of development workflows.
Take ownership of technical challenges in a fast-moving environment where priorities can evolve quickly.
What We’re Looking For
The team places significant emphasis on technical ability, problem-solving, learning velocity, and ownership rather than a rigid checklist of previous experience.
You’ll ideally bring:
Strong software engineering fundamentals and the ability to build clean, reliable, production-quality systems.
A strong general technical background, with an interest in machine learning, AI, or related disciplines.
Excellent analytical and problem-solving skills.
The ability to learn unfamiliar technologies and technical concepts quickly.
A practical, hands-on approach to engineering, with the initiative to take projects from concept through implementation.
High levels of ownership, adaptability, and intellectual curiosity.
The motivation to work closely with a small, ambitious team tackling technically challenging problems.
Experience in one or more of the following would be advantageous:
Machine learning engineering or research engineering.
Reinforcement learning and simulation environments.
Production ML systems or large-scale software infrastructure.
GPU-accelerated computing and simulation.
Model training, post-training, or evaluation.
Robotics and embodied AI.
A background in robotics is not essential. The priority is strong software and AI capability rather than a purely mechanical, electrical, or controls-focused background.
Candidates with a bachelor's or master's degree, a PhD, or equivalent practical experience are all welcome to apply. Exceptional early-career engineers will be considered alongside more experienced candidates.
The Technical Environment
The team is working with modern AI training and simulation technologies, including GPU-accelerated simulation and model post-training frameworks.
Technologies discussed include:
Python and modern software engineering tools.
Reinforcement learning and simulation workflows.
GPU-accelerated simulation, including Newton and MuJoCo Warp.
Model post-training tools, including Tinker.
Model evaluation, benchmarking, and performance optimisation.
The precise stack is flexible. Strong underlying engineering ability and the capacity to pick up new tools quickly are more important than prior experience with every technology listed.
Why Join?
Work at the frontier of AI. Contribute to the environments and infrastructure used to train and evaluate increasingly capable AI models.
Build at meaningful scale. Work with a company that combines simulation-based development with substantial real-world robotics infrastructure, allowing models and environments to be evaluated beyond purely theoretical settings.
Take ownership early. Join a small technical team where your work will have a direct impact on the product, engineering standards, and future direction of the business.
Work closely with research talent. Collaborate with highly technical colleagues to turn research ideas into scalable, production-ready systems.
Help shape the engineering culture. Play a meaningful role in raising software quality and establishing practices that support the next stage of growth.
Grow with an ambitious business. Join at an early stage, with competitive compensation, equity participation, and the opportunity to take on increasing technical responsibility.
Working Environment
This is a full-time, office-based role in San Francisco. The team values close collaboration, fast iteration, high ownership, and a strong commitment to delivering results.
The environment is intense and best suited to people who enjoy working hard, tackling difficult problems, and learning rapidly alongside ambitious engineers and researchers. Candidates should be comfortable with a demanding startup environment and a high level of commitment to the work.
Compensation
The salary range for this position is $120,000–$220,000 base salary, plus equity, depending on technical ability, experience, and the scope of the role.
Interested?
If you’re a strong ML engineer who wants to build the infrastructure behind next-generation AI systems, we’d love to hear from you.
Whether you come from a traditional software engineering background, ML engineering, research engineering, or a related technical discipline, we’re interested in people who combine excellent fundamentals with the ability to learn quickly and deliver high-quality work.
 Rosie Collins
United States
Senior Engineer, ML
Permanent
Senior Engineer
Remote (US) | Permanent | Base salary plus bonus and equity eligibility
DeepRec has partnered with an autonomous vehicle company to hire a Senior Engineer for its ML data services team. You'll build the services and pipelines that turn terabytes of raw data into the datasets autonomy ML teams train and test on.
THE OPPORTUNITY
Every model the autonomy teams ship depends on what your systems deliver. You'll own the backend that stores and serves it, and help shape how the team plans and builds.
WHAT YOU'LL DO
• Design and build RESTful APIs and microservices for labelling and annotation workflows
• Build and run scalable cloud ETL pipelines delivering training and simulation datasets
• Own critical, highly available backend services handling terabytes of data
• Set objectives, timelines and deliverables with engineering leadership and stakeholders
• Design monitoring and observability for the MLOps pipelines
• Mentor junior engineers through pairing sessions on code quality and SDLC practice
WHAT YOU'LL BRING
Essential
• Significant Python backend experience building REST APIs and microservices
• Production AWS experience, such as DynamoDB, EKS, Lambda or S3
• Pipeline orchestration with Step Functions, Airflow or Prefect
• Experience mentoring engineers and planning roadmaps with cross-functional teams
Desirable
• Large-scale processing with Ray, Beam or Spark
• Vector databases for embedding retrieval
• Autonomous driving industry experience
We encourage you to apply even if you don't meet every requirement. The right mindset matters as much as the right CV.
WHAT'S IN IT FOR YOU
• Base salary plus bonus and equity eligibility
• Fully remote within the US
• Medical, dental and vision cover, plus health savings account options
• 401(k) with company match, life insurance and pet insurance
• Ownership of critical services the autonomy ML teams rely on
APPLY NOW
If building the data foundations behind self-driving systems sounds like your kind of problem, we'd love to hear from you. Apply now and start the conversation.
 Sam Warwick
United States
Principal Engineer, Simulation Infrastructure
Permanent
Principal Engineer Team Lead
Hybrid, US (occasional on-site time at company offices) | Permanent | Up to 10% travel
DeepRec has partnered with an autonomous vehicle company to hire a Principal Engineer Team Lead for its simulation infrastructure team. You'll lead the engineers behind cloud infrastructure that handles millions of simulation runs a month and feeds directly into release gating.
THE OPPORTUNITY
Your infrastructure sets how fast autonomy engineers can test changes and how confidently the company ships. You'll own the technical roadmap and the team that delivers it.
WHAT YOU'LL DO
• Lead, mentor and grow a multi-site team of infrastructure engineers
• Set the multi-year technical roadmap for the team
• Architect high-throughput, multi-cluster orchestration for millions of monthly simulation runs
• Cut AWS spend through EC2 sizing and spot queues with automated failover
• Build plug-and-play engine abstractions and System Under Test tooling
• Own cost, throughput and queue observability, with real-time dashboards
• Lead postmortems and root-cause analysis to improve test stability
WHAT YOU'LL BRING
Essential
• Significant experience in autonomous vehicles, robotics or large-scale cloud infrastructure
• Proven track record leading engineering teams and setting technical roadmaps
• Production Python and C++ in Linux environments
• Deep AWS scaling experience, including EC2, spot instances and cost management
Desirable
• Autonomous driving simulation, such as log sim, closed loop or scenario formats
• GitLab CI/CD, Docker and Airflow orchestration
• HIL bench integration, CAN protocols or camera and LiDAR sensor simulation
We encourage you to apply even if you don't meet every requirement. The right mindset matters as much as the right CV.
WHAT'S IN IT FOR YOU
• Principal-level ownership of a multi-year technical roadmap
• A team at the centre of how autonomy software gets released
• Scale problems few teams face, with millions of runs each month
• Hybrid working with occasional on-site collaboration
• Medical, dental and vision cover, plus 401(k) with company match
APPLY NOW
If leading the infrastructure that decides how autonomy software ships sounds like your next step, we'd love to hear from you. Apply now and start the conversation.
Sam WarwickMunich, Germany
Machine Learning & Cloud Infra Engineer
Permanent
Machine Learning & Cloud Infra Engineer
Munich (On-site) | Full time
About the Company
Our client is an early-stage AI company building generative models that learn the physics and geometry of the real world in 3D, rather than working from flat images. The work is aimed at use cases in robotics, AR/VR, gaming, and film.
The team is small, and researchers and engineers work closely together on both the models and the systems that take them into products.
About the Role
This role owns the infrastructure behind the company’s training and evaluation of large diffusion-based generative models. That covers GPU clusters, storage, orchestration, and the path to model serving.
It is hands-on and systems-focused. You will work directly with the researchers who use what you build, so priorities come from real training problems rather than a roadmap handed down to you.
What You’ll Do
Own and evolve the ML and cloud infrastructure used to train and evaluate large models
Provision, scale, and maintain multi-node, multi-GPU environments on cloud and/or on-prem, including scheduling, quotas, and capacity planning
Support distributed training (PyTorch DDP/FSDP, NCCL) and keep large runs stable, performant, and reproducible
Build and optimize storage and networking for petabyte-scale datasets
Deploy workloads with Docker and Kubernetes, and manage infrastructure-as-code with Terraform
Set up monitoring, logging, and alerting for cluster health, job performance, and cost, and define SLOs and incident response practices
Manage secrets, IAM, and network security across research and production
Work with researchers to unblock training and support the move from research to served models
What We’re Looking For
3+ years in infrastructure, platform, or cloud engineering
Hands-on GPU performance debugging (CUDA/NCCL concepts, utilization, network bottlenecks, profiling)
Strong experience running AWS, GCP, or Azure, including networking, IAM, and cost management
Proficiency with Docker, Kubernetes, and Terraform
Strong scripting and automation skills in Python plus Bash or PowerShell
Familiarity with distributed training in PyTorch (DDP/FSDP or similar)
Experience with observability tooling such as Prometheus/Grafana, OpenTelemetry, or ELK
Experience building CI/CD for infrastructure and ML workflows
Nice to Have
Prior ML infrastructure experience supporting large-scale training
Experience running on-prem GPU clusters alongside cloud capacity
Experience with model evaluation and serving infrastructure
Experience running on-call and incident response
Why Join
Ownership. You will be responsible for the infrastructure behind a research program, not one corner of a larger platform.
Scale. Multi-node GPU training and petabyte-scale datasets are part of the daily work.
Proximity to research. You will work alongside the people who depend on your systems.
Influence. In a small team, your views on tooling and architecture carry weight.
What to Expect
This is an on-site role in Munich. Expect to work across the stack, from cluster operations to developer tooling, and to share responsibility for reliability.
If this sounds relevant, get in touch for a confidential conversation.
 Curtis Holben
London, United Kingdom
Founding Research Scientist/Engineer
Permanent
Founding Research Scientist
Location: London (exceptional candidates considered remote)
Compensation: £200k-£500k base + 3-6% equity
About the company
A stealth-stage AI startup founded by an exceptional researcher, with a major funding round on the horizon. Details are shared in confidence during the conversation.
About the role
This is a founding hire. You’ll independently drive research, develop original ideas and take them from initial hypothesis to meaningful outcomes. You’ll help shape the research direction from day one.
What you’ll do
Lead and own research projects end to end
Develop original ideas and turn them into tangible results
Help set the research agenda and priorities for the company
Work closely with the founding team to shape what gets built
What we’re looking for
Deep expertise in at least one of the following areas:
LLM post-training and evaluation
Learning from human and AI feedback
Personalisation and recommender systems
Adjacent areas are welcome
Alongside that, you’ll have:
A PhD in a related field
A strong research track record
Experience in a top research environment at the frontier, ideally Staff level or above
What’s on offer
£200k-£500k base salary, depending on experience
3-6% equity, offering genuine founding-level ownership
The chance to shape a company’s research direction from the start
Backing from a world-class advisory network
 Jonathan Harrold
London, United Kingdom
Machine Learning & Cloud Infra Engineer - London
Permanent
Machine Learning & Cloud Infra Engineer
London (On-site) | Full time
About the Company
Our client is an early-stage AI company building generative models that learn the physics and geometry of the real world in 3D, rather than working from flat images. The work is aimed at use cases in robotics, AR/VR, gaming, and film.
The team is small, and researchers and engineers work closely together on both the models and the systems that take them into products.
About the Role
This role owns the infrastructure behind the company’s training and evaluation of large diffusion-based generative models. That covers GPU clusters, storage, orchestration, and the path to model serving.
It is hands-on and systems-focused. You will work directly with the researchers who use what you build, so priorities come from real training problems rather than a roadmap handed down to you.
What You’ll Do
Own and evolve the ML and cloud infrastructure used to train and evaluate large models
Provision, scale, and maintain multi-node, multi-GPU environments on cloud and/or on-prem, including scheduling, quotas, and capacity planning
Support distributed training (PyTorch DDP/FSDP, NCCL) and keep large runs stable, performant, and reproducible
Build and optimize storage and networking for petabyte-scale datasets
Deploy workloads with Docker and Kubernetes, and manage infrastructure-as-code with Terraform
Set up monitoring, logging, and alerting for cluster health, job performance, and cost, and define SLOs and incident response practices
Manage secrets, IAM, and network security across research and production
Work with researchers to unblock training and support the move from research to served models
What We’re Looking For
3+ years in infrastructure, platform, or cloud engineering
Hands-on GPU performance debugging (CUDA/NCCL concepts, utilization, network bottlenecks, profiling)
Strong experience running AWS, GCP, or Azure, including networking, IAM, and cost management
Proficiency with Docker, Kubernetes, and Terraform
Strong scripting and automation skills in Python plus Bash or PowerShell
Familiarity with distributed training in PyTorch (DDP/FSDP or similar)
Experience with observability tooling such as Prometheus/Grafana, OpenTelemetry, or ELK
Experience building CI/CD for infrastructure and ML workflows
Nice to Have
Prior ML infrastructure experience supporting large-scale training
Experience running on-prem GPU clusters alongside cloud capacity
Experience with model evaluation and serving infrastructure
Experience running on-call and incident response
Why Join
Ownership. You will be responsible for the infrastructure behind a research program, not one corner of a larger platform.
Scale. Multi-node GPU training and petabyte-scale datasets are part of the daily work.
Proximity to research. You will work alongside the people who depend on your systems.
Influence. In a small team, your views on tooling and architecture carry weight.
What to Expect
This is an on-site role in London or Munich. Expect to work across the stack, from cluster operations to developer tooling, and to share responsibility for reliability.
If this sounds relevant, get in touch for a confidential conversation.
Curtis HolbenMunich, Germany
Robot Autonomy Engineer
Permanent
Staff Robot Learning Engineer | Germany | Hybrid | Full-time
You’ve already trained and deployed learning-based policies on real robots. Now you can help bring the next generation of humanoid robotics into the real world.
You’ll join an ambitious robotics company developing general-purpose humanoids, building robot-learning systems that work beyond the simulator. You’ll train and improve policies, develop data pipelines, run experiments on physical hardware and tackle the challenges of reliable sim-to-real transfer.
This is a hands-on engineering role for someone who combines strong machine-learning fundamentals with practical robotics experience. You’ll work across imitation learning, reinforcement learning and emerging vision-language-action models, helping turn promising approaches into robust robotic capabilities.
You’ll need:
Hands-on experience training robot policies using reinforcement learning, imitation learning or learning from demonstration.
Proven experience deploying learned policies on physical robots.
Strong Python and PyTorch skills, with good C++.
Experience with robot data collection, simulation and sim-to-real transfer.
A solid understanding of robot control, action representations and closed-loop policy execution.
Experience with humanoid manipulation, teleoperation, diffusion policies, vision-language-action models or real-time action chunking would be a strong advantage.
If you want to turn advances in robot learning into capable, reliable humanoid robots, let’s chat!
 Paddy Hobson
London, United Kingdom
Tech Lead
Contract
Tech Lead – Data Platform12-month contract | Fully RemoteWe are working with an early-stage technology company building a data-intensive B2B SaaS product for enterprise customers.The platform combines large-scale data pipelines, analytical and modelling capabilities, and a modern web application. The engineering team is small, highly technical and moving quickly as the product scales.We are looking for a hands-on Tech Lead to take ownership of the technical direction, architecture and engineering delivery across the platform.What you'll doOwn the technical architecture across data, backend and product.Lead a small engineering team across delivery, priorities and technical direction.Translate product requirements into practical technical plans.Remain hands-on, writing and reviewing production code.Establish strong engineering practices around testing, releases, observability and security.Work with enterprise customers on technical and security requirements.Help shape the product and technology roadmap.Must-haveSignificant hands-on engineering experience as a Tech Lead, Founding Engineer, Staff Engineer or similar.Proven experience building and taking a data-driven product from prototype into production.Strong experience with data platforms, production pipelines and cloud data warehouses.Strong B2B SaaS architecture experience, including multi-tenancy, security and data protection.Strong TypeScript and React/Next.js experience.Experience working in a fast-moving startup or scale-up environment.Entrepreneurial mindset with the ability to operate independently and comfortably with ambiguity.Strong software engineering practices and experience using AI-assisted development tools.Nice to haveExperience working in an early-stage startup through Series A or similar growth stage.Snowflake or equivalent cloud data warehouse experience.Experience with complex operational or event-based data.Process mining, simulation or Operations Research experience.Experience building analytical or data-intensive B2B products.Experience working with production AI/LLM features.
 Sam Oliver